Overview
What is the functionality of AWS Data Pipeline and how does it operate? AWS Data Pipeline is a web service that facilitates the reliable movement and processing of data between various AWS compute and storage services, as well as on-premises data sources, at specified intervals. AWS Data Pipeline allows for seamless distribution of tasks to single or multiple machines, either in a serial or parallel manner. With the adaptable design of AWS Data Pipeline, processing a large number of files is as effortless as processing a single file. Users can utilize the activities and preconditions provided by AWS, as well as create their own custom ones. This enables configuration of an AWS Data Pipeline to perform actions such as running Amazon EMR jobs, executing SQL queries directly against databases, or running custom applications on Amazon EC2 or in a personal datacenter.
Expert review of AWS Data Pipeline
AWS Data Pipeline Review
Introduction
AWS Data Pipeline is a powerful and versatile cloud-based service offered by Amazon Web Services (AWS). It allows users to easily create, schedule, and manage data-driven workflows, making it an essential tool for organizations that deal with large volumes of data. In this review, we will explore the key features, use cases, pros, cons, and provide a recommendation for AWS Data Pipeline.
Key Takeaways
- AWS Data Pipeline simplifies the process of orchestrating complex data workflows.
- It supports a wide range of data sources and destinations, enabling seamless integration with various AWS services.
- Users can easily schedule and monitor data processing activities through a user-friendly interface.
- AWS Data Pipeline offers fault tolerance and error handling mechanisms, ensuring reliable and consistent data workflows.
- The service provides extensive monitoring and logging capabilities for tracking the progress of data pipelines.
Table of Features
| Feature | Description |
|---|---|
| Broad data integration | Supports integration with various AWS services, databases, and external systems. |
| Workflow orchestration | Enables the creation and management of complex data-driven workflows. |
| Scheduling and monitoring | Allows users to schedule and monitor data processing activities. |
| Fault tolerance | Provides built-in fault tolerance and error handling mechanisms. |
| Monitoring and logging | Offers extensive monitoring and logging capabilities for data pipelines. |
| Security | Provides secure data transfer and encryption options. |
Use Cases
AWS Data Pipeline can be utilized in various scenarios and use cases, such as:
- Data ETL (Extract, Transform, Load): Automate the process of extracting data from different sources, transforming it, and loading it into a data warehouse or analytics platform.
- Data Backup and Restore: Create automated workflows to backup data from databases or storage systems and restore it when needed.
- Data Migration: Seamlessly move data between different systems or databases, ensuring minimal downtime and data loss.
- Data Processing and Analysis: Streamline the processing and analysis of large datasets, leveraging the scalability and power of AWS services like Amazon EMR or AWS Lambda.
- Data Import/Export: Automate the import or export of data from external sources, such as third-party applications or partner systems.
Pros
- Ease of Use: AWS Data Pipeline offers a user-friendly interface with a drag-and-drop visual editor, making it accessible to users with varying technical expertise.
- Integration with AWS Services: The service seamlessly integrates with various AWS services, including Amazon S3, Amazon Redshift, Amazon EMR, and more, allowing users to leverage existing infrastructure.
- Scalability: AWS Data Pipeline can handle large-scale data workflows, enabling organizations to process and analyze massive amounts of data efficiently.
- Fault Tolerance: The service provides built-in fault tolerance and error handling mechanisms, ensuring data integrity and minimizing disruptions.
- Monitoring and Logging: AWS Data Pipeline offers comprehensive monitoring and logging capabilities, allowing users to track the progress of data pipelines and troubleshoot any issues effectively.
Cons
- Learning Curve: Although the user interface is intuitive, mastering the advanced features of AWS Data Pipeline may require some learning and experimentation.
- Limited Customization: While the service provides a broad range of features, it may lack certain customization options that some users may require for specific use cases.
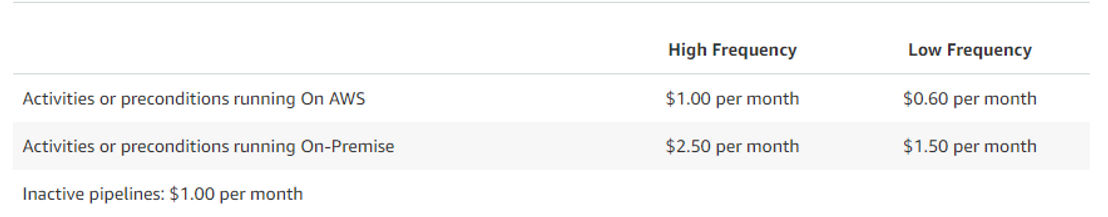
- Pricing Complexity: AWS Data Pipeline pricing can be complex, as it depends on factors such as data volume, pipeline complexity, and usage frequency. Users need to carefully plan their workflows to optimize costs.
Recommendation
AWS Data Pipeline is a robust and feature-rich service that simplifies the management of data workflows in the cloud. Its broad integration capabilities, fault tolerance mechanisms, and comprehensive monitoring features make it a valuable tool for organizations dealing with data-intensive operations. However, users should be prepared to invest time in learning the service and carefully plan their workflows to optimize costs. Overall, AWS Data Pipeline is highly recommended for organizations seeking an efficient and scalable solution for orchestrating their data pipelines in the cloud.
AWS Data Pipeline pricing model
Subscription
Features
- Metadata Management
- Compliance Tracking
- Version Control
Technical details
- Support: Online
- Customer Type: Large Enterprises Medium Business Small Business
- Deployment: SaaS/Web/Cloud
- Official Website: https://aws.amazon.com/datapipeline/
- Category: ETL Tools
Related software

Apibit summaries are researched from vendor documentation and public information. Features and prices change often, so confirm details with the vendor. See our editorial policy and advertiser disclosure.